
AI chips are getting faster, but raw compute is only useful when data can reach those chips quickly enough. That’s where high bandwidth memory comes in.
Large language models constantly move model weights, activations and cached data between memory and compute units. When memory cannot keep pace, expensive GPU cores can spend time waiting for data. HBM memory tackles this bottleneck by placing stacked DRAM close to the processor and connecting it through an unusually wide interface.
In this post, I’ll break down what is high bandwidth memory, how HBM bandwidth differs from conventional memory, why AI GPUs depend on it, how HBM4 changes the architecture, and the manufacturing and supply challenges shaping the next generation of AI infrastructure.
Also read: Why the Cerebras IPO is Wall Street’s Biggest AI Story in 2026
Key Takeaways
- High bandwidth memory uses vertically stacked DRAM and very wide interfaces to move far more data between memory and AI accelerators than conventional memory designs.
- HBM bandwidth helps GPUs overcome memory bottlenecks, while HBM capacity determines how much of a model and its working data can stay close to compute.
- HBM4 doubles the interface width of HBM3-class memory from 1,024 to 2,048 bits, pushing per-stack bandwidth into multiple terabytes per second.
- HBM is powerful but complex. Advanced packaging, heat, yield, cost and supply constraints are becoming important limits on how quickly AI infrastructure can scale.
What is High Bandwidth Memory (HBM)?

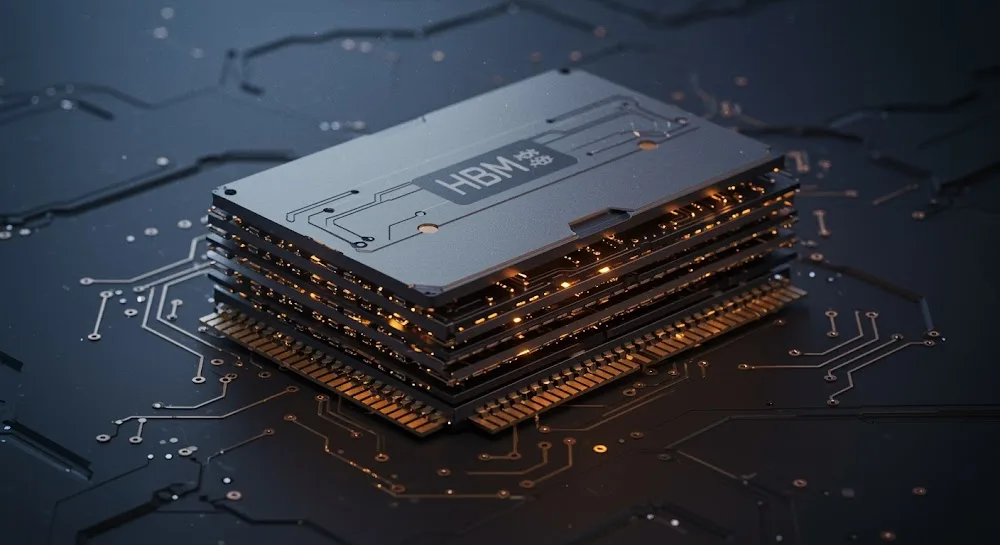
I think of HBM as DRAM redesigned for speed. Instead of placing memory chips farther away across the motherboard, it stacks several DRAM layers vertically and positions them close to the GPU, TPU or other AI accelerator.
That means data has a much shorter distance to travel, while thousands of connections allow large amounts of it to move at the same time.
This “wide and close” design is what makes high bandwidth memory so useful for AI. Samsung describes HBM as stacked DRAM connected through TSVs and designed for demanding, highly parallel workloads such as AI training and high-performance computing.
How HBM Uses 3D-Stacked DRAM
HBM is like memory built upward instead of spread out across a board. Several thin DRAM layers are stacked on top of each other, with tiny vertical connections called through-silicon vias, or TSVs, carrying data and power between them.
The stack then sits right next to the processor on an interposer, which creates very short, dense connections between memory and compute. Rambus describes this as 3D stacking inside the memory combined with 2.5D integration at the package level.
In practice, this design gives HBM memory much higher throughput because data can travel across a very wide interface without depending only on faster clock speeds.
HBM vs DDR and GDDR: Architecture, Bandwidth, and Power
Take a look at this table for a quick comparison.
| Feature | HBM | DDR | GDDR |
| Main use | AI accelerators and HPC GPUs | CPUs and system memory | Graphics cards and some accelerators |
| Layout | Vertically stacked beside processor | DIMMs or chips on board | Chips positioned around GPU |
| Interface | Extremely wide | Narrower | Wider than DDR, narrower than HBM |
| Bandwidth approach | Many parallel connections | General-purpose memory interface | High per-pin signalling speed |
| Power and distance | Short package-level links | Longer board-level links | High-speed board-level links |
Understanding HBM Bandwidth, Bus Width, Channels, and Interposer Connectivity
HBM bandwidth is the amount of data that can move between a memory stack and processor each second. It depends on per-pin speed and the number of connections working in parallel.
HBM3E uses a 1,024-bit data interface. HBM4 doubles that interface to 2,048 bits. Rambus notes that once command, address and clock signals are included, an HBM4 connection can require roughly 3,000 traces between a memory device and processor.
- Bus width changes the scale of data movement. HBM gains much of its performance by transferring data across hundreds or thousands of paths at once instead of depending only on extreme per-pin speeds.
- More bandwidth does not guarantee unlimited performance. A workload must be able to use that bandwidth, and the processor, memory controller, software and data layout all influence how much real throughput an application achieves.
- Channels help HBM work in parallel. Each stack is divided into accessible channels, allowing controllers to serve multiple memory requests at once. That parallelism suits AI workloads that continuously move large blocks of model data.
Micron’s current HBM4, for example, uses a 2,048-pin interface above 11 Gb/s and delivers more than 2.8 TB/s per stack. Samsung lists up to 3.3 TB/s for its commercial HBM4.
Why AI Infrastructure Depends on High Bandwidth Memory
The Memory Wall: Why Faster AI Chips Need Faster Memory
AI accelerators contain enormous numbers of compute units designed to perform operations in parallel. But those units need a steady supply of data.
If a GPU can calculate faster than memory can deliver the next weights or values, compute cores wait. This gap between compute capability and memory movement is often called the memory wall. Micron describes the same problem as the growing disparity between processor speeds and memory bandwidth or latency, particularly for AI training and inference.
High bandwidth memory addresses that problem directly. An HBM memory GPU system gives the accelerator a fast local memory pool, which matters in training and inference because model weights and working data are accessed repeatedly.
Also read: The 2026 Chip Shortage Explained: How AI is Making Consumer Tech More Expensive
HBM Capacity vs Bandwidth: Model Weights, Activations, and KV Cache
Capacity and bandwidth are related, but they solve different problems.
| Memory need | What it means | Why AI needs it |
| Capacity | How much data can fit in HBM | Holds model weights, activations, optimizer data and KV cache |
| Bandwidth | How quickly data can move | Feeds GPU cores fast enough to sustain parallel computation |
| Model weights | Learned parameters | Large models can require tens or hundreds of gigabytes |
| Activations | Intermediate values created during processing | Training can require substantial activation memory |
| KV cache | Stored keys and values from earlier tokens | Grows as context length increases during inference |
Capacity determines how much data memory can hold, while bandwidth determines how much of that data can flow each second.
For a fixed transformer model and batch, KV-cache storage generally grows roughly linearly with sequence length. Longer contexts therefore raise capacity pressure even when model weights stay unchanged.
I think of bandwidth as traffic flow and capacity as parking space. An accelerator can hold a large model but still underperform if data moves too slowly, or have fast memory but run out of local capacity. An HBM memory GPU therefore needs both.
How GPUs and AI Accelerators Use HBM to Keep Compute Cores Fed
Modern AI accelerators place multiple HBM stacks around the processor package, while memory controllers spread reads and writes across channels. AMD’s Instinct MI350 Series, for example, provides 288 GB of HBM3E and up to 8 TB/s of peak theoretical memory bandwidth per GPU.
It is also important to separate local memory from networking:
- HBM feeds the individual accelerator. It handles high-speed movement of weights, activations and other working data between a GPU or accelerator and its local memory.
- Interconnects link accelerators together. Technologies such as NVLink, Infinity Fabric, Ethernet and InfiniBand move data between GPUs, servers or racks when models and workloads are distributed across multiple devices.
Large AI systems need both local HBM bandwidth and fast accelerator networking to scale effectively.
Energy Efficiency and Thermal Benefits in High-Density AI Data Centers
Moving data consumes energy. High bandwidth memory helps by using short connections and a wide interface, moving many bits in parallel over package-level paths instead of longer board traces. Micron explains that HBM’s wide bus allows high throughput at lower operating frequencies than conventional alternatives such as GDDR.
Micron says its HBM4 provides more than 20% better power efficiency than its HBM3E when compared at similar speeds, alongside more than 2.8 TB/s of bandwidth per stack.
HBM still creates a thermal challenge because dense memory stacks sit beside power-hungry processors, making cooling and package design increasingly important.
How HBM Works with Modern AI Accelerators
The Role of 2.5D/3D Packaging, Interposers, and Through-Silicon Vias
The “3D” part happens inside the HBM device. DRAM dies are stacked vertically, while TSVs provide electrical connections between those layers.
The “2.5D” part refers to placing HBM stacks and the processor beside one another on an interposer. The interposer contains extremely fine wiring that can connect thousands of memory signals to the accelerator.
Roughly 3,000 traces may be required once its 2,048 data traces are combined with command, address and clock connections. A conventional PCB cannot practically support that density, so the interposer becomes essential.
How HBM Connects to GPUs, TPUs, and AI Accelerators
Memory controllers inside a GPU or custom accelerator communicate with each HBM stack across multiple channels. Designers choose how many stacks to attach and balance bandwidth, capacity, package area, power and cost.
HBM4 makes this relationship even tighter. The generation doubles the HBM3-class interface width from 1,024 to 2,048 bits, increasing the number of I/O connections between memory and processor.
Samsung announced on February 12, 2026 that it had begun mass production of HBM4 and shipped commercial products to customers. Its design uses a 4 nm logic base die and runs consistently at 11.7 Gb/s, with capability up to 13 Gb/s.
Plus, Micron announced in March that volume shipments of its 36 GB, 12-high HBM4 had begun in the first quarter of 2026. The product delivers more than 2.8 TB/s per stack.
The HBM memory GPU relationship increasingly looks like co-design, with memory treated as part of the accelerator package itself.
Evolution of HBM: From HBM1 to HBM4

HBM1 to HBM3E: How Capacity and Bandwidth Increased
The original HBM generation used a 1,024-bit interface and delivered 128 GB/s per stack at a 1 Gb/s data rate. Later generations increased speed, stack height and capacity while keeping the wide-interface idea. Rambus lists HBM2 at 256 GB/s, HBM3 at 819 GB/s and HBM3E at up to 1,229 GB/s per device. HBM4 then doubles the interface width.
HBM4: Wider Interfaces, Logic Base Dies, and Next-Generation AI Accelerators
HBM4 isn’t merely a future standard. As of July 2026, commercial products are shipping.
Samsung’s February 2026 announcement said its HBM4 had entered mass production and commercial shipment. Samsung’s product page lists a 36 GB 12-high stack, 2,048 I/O pins and bandwidth up to 3,300 GB/s.
Micron began volume shipment of its 36 GB 12-high HBM4 in the first quarter of 2026. It reports more than 11 Gb/s per pin, more than 2.8 TB/s per stack and over 20% better power efficiency than its HBM3E.
The roadmap is already moving again. Samsung began shipping 12-layer HBM4E samples on May 29, 2026, and SK hynix announced its own samples on June 18; both reported speeds up to 16 Gb/s per pin.
Challenges of Scaling High Bandwidth Memory
Manufacturing Complexity, Yield, and Advanced Packaging
HBM is difficult to manufacture because thin DRAM dies must be stacked and bonded accurately, TSVs must stay reliable, and the completed package must connect cleanly to the accelerator.
HBM is one of the more challenging memory products to produce because ultra-thin dies are linked through thousands of TSVs. Higher stacks also increase pressure on yield, warping and thermal control.
HBM Cost, Supply Constraints, and the AI Memory Shortage
AI demand has turned HBM into a strategic supply-chain component.
TechInsights reported in February 2026 that HBM consumes roughly three to four times as many wafers per bit as DDR5. It argued that growing HBM production is diverting capacity and contributing to tighter DRAM supply, longer lead times and higher costs across data-centre infrastructure.
According to Accuris reports in May 2026, HBM represented 23% of total DRAM wafer capacity, citing industry data, and that its own tracking showed semiconductor lead times reaching 40 weeks in March 2026.
Power Density, Cooling, and Thermal Management
More layers and higher data rates mean more heat in a small space. HBM’s short links improve data-movement efficiency, but the stacks sit beside power-hungry accelerators. Thermal resistance, bonding materials, package design and cooling therefore influence whether the system can sustain its available HBM bandwidth.
Beyond HBM: PIM, CXL, and the Future of AI Memory
Processing-in-Memory: Moving Compute Closer to Data
Processing-in-memory, or PIM, moves some computing functions into or close to memory. The idea is to reduce unnecessary data movement by performing selected calculations near stored data. Samsung has demonstrated HBM-PIM by integrating AI processing capability into HBM for AI and high-performance computing. PIM isn’t a GPU replacement and is more of a complementary approach for memory-bound work.
CXL Memory Expansion and Pooling
Compute Express Link, or CXL, tackles a different problem. It is a high-speed coherent interconnect connecting processors, memory devices and accelerators, and it can support memory expansion, sharing and pooling.
Pooled memory can be dynamically allocated by a memory controller. CXL-attached memory does not replace local HBM; it can form another tier for data that needs capacity but not the same local throughput.
Will PIM and CXL Replace HBM or Complement It?
I’d say that the more likely answer is complement.
AI infrastructure increasingly needs multiple memory tiers rather than one universal technology. High bandwidth memory handles extreme local throughput. CXL can add flexible capacity. PIM can reduce movement for selected calculations.
Final Thoughts
The clearest way to understand high bandwidth memory is to probably think about the gap between how fast AI processors can do the maths and how quickly memory can keep feeding them data.
HBM4 pushes that idea further. The first commercial HBM4 products in 2026 doubled the interface width to 2,048 bits and pushed per-stack bandwidth beyond 2 TB/s, bringing memory and accelerator design even closer together.
The main takeaway is that faster GPUs alone aren’t enough. They also need enough memory capacity, enough bandwidth and the right packaging to move data efficiently. That’s why HBM has become such an important part of modern AI infrastructure.
For more info on tech and AI, visit Yaabot.
FAQs
High bandwidth memory is stacked DRAM placed close to a processor and connected through a wide interface. It is designed to deliver extremely high memory throughput for GPUs, AI accelerators and high-performance computing.
HBM is a type of DRAM. That is why HBM vs DRAM is not a literal technology comparison. In practice, HBM vs DRAM usually means comparing HBM architecture with conventional DDR-based memory.
An HBM memory GPU gets high local bandwidth and substantial capacity close to compute. That helps GPU cores access model weights, activations and cached data without constantly depending on slower system-memory transfers.
HBM bandwidth is the amount of data that can move between memory and a processor each second. HBM3E can exceed 1 TB/s per stack, while current HBM4 products reach beyond 2 TB/s.
HBM4 is the latest commercial generation of high bandwidth memory in 2026. It doubles the HBM3-class data interface from 1,024 to 2,048 bits and significantly raises per-stack bandwidth.
No. HBM is optimised for bandwidth-intensive accelerators, while DDR remains practical for large, general-purpose system memory. AI servers are more likely to use multiple memory technologies for different parts of the memory hierarchy.
