
I’ve lost count of how many scrapers I’ve had to rebuild because a client’s site swapped a <div> for a <section>. That’s basically the whole story: traditional web scraping tools pull data by matching fixed HTML patterns, and AI crawling systems read a page the way a person would, figuring out what a “price” or a “product name” is instead of just where it happens to sit in the markup. One survives a redesign. The other doesn’t.
I’ve maintained both kinds of pipelines. CSS-selector scrapers that snapped the moment a dev team shifted to a new frontend, and LLM-based extractors that crawled through three redesigns without me touching a single line. The stats below come from Cloudflare, Imperva, and a few industry trackers, so you don’t just have to take my word for it.
A Quick Brief
AI crawling tools use a language model to interpret page content, so they adapt when the structure changes. Traditional web scraping tools, BeautifulSoup, Scrapy, raw XPath/CSS selectors, pull data from fixed positions in the HTML, and they break the moment that structure moves. The gap shows up in the numbers: AI-based extraction is now hitting accuracy up to 99.5% on unorganized, JavaScript-heavy sites, while teams running traditional scrapers say they’re burning 20–30% of their engineering time just keeping selectors alive.
What Are Traditional Web Scraping Tools?
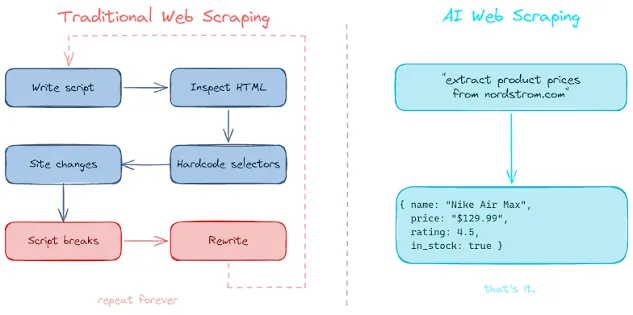
A traditional scraper (Scrapy, Cheerio, Selenium, Puppeteer, or plain requests + BeautifulSoup) runs on three instructions: fetch the page, find this selector, pull this text. It’s precise. It’s cheap to run at scale. Same input, same output, every time. The problem is that it doesn’t actually know a “price” is a price, it only knows .price_color is a string sitting at a specific spot in the DOM. Rename that class and the pipeline goes quiet. No error, no crash, just an empty result set that someone notices a day later when the numbers look wrong.
Worth separating two different things here: the tool doing the scraping and the tool used to write it. Someone building this kind of selector-based scraper today is likely leaning on an AI coding assistant to draft and debug the script itself, which speeds up code writing, but it doesn’t change the underlying fragility. The scraper still only knows .price_color, whether a human or an AI assistant typed that selector.
What Is an AI Website Crawler (and AI Site Crawler)?
An AI website crawler pairs a headless browser (to render JavaScript, scroll, click) with a model that actually reads the rendered content. Instead of a selector, you give it plain English: “extract the product name, price, and availability.” It finds the equivalent fields regardless of the underlying markup. This is also roughly how the current wave of AI web crawling bots from OpenAI, Anthropic, Google, and Perplexity operate; they’re not matching keyword strings the way Googlebot used to. They’re retrieving and breaking down whole pages, either to answer a live query or to feed a training run.
If you’re actually building or buying an extraction pipeline, the tool names are split by what they’re for. Firecrawl and Jina Reader convert an entire page into clean Markdown or text for feeding into an LLM, no field-level extraction, just a cleaned-up version of the page. Spidra, and Thunderbit go the other direction: you describe specific fields (name, price, job title) and get back structured JSON. Bright Data and Apify sit in between, established scraping infrastructure with an AI extraction layer bolted on for the harder pages. None of these are interchangeable; choosing one depends on whether you need a full page or a handful of fields.
Key Technical Differences
| Dimension | Traditional Web Scrapping Tools | AI Crawlers |
| Extraction logic | Fixed CSS/XPath selectors | Reads and interprets content |
| Breaks on redesign | Yes, immediately | Usually not, they adapt to the redesign |
| Setup | Code, per site | Plain-language instructions |
| Cost per page | Near-zero (compute only) | Fractions of a cent to a few cents, scales with volume |
| Best fit | Large, stable, high-volume jobs | Unorganized, dynamic, frequently-changing sites |
| Maintenance | Constant selector fixes | Mostly hands-off |
| Transparency | You can see every rule | Harder to audit exactly why it picked what it picked |
Why Engineering Teams Crawl for AI: Key Use Cases
Most teams that crawl for AI purposes aren’t after a single page of data. They’re building a training corpus, feeding a chatbot’s retrieval index, or keeping an answer engine up to date. That’s a different job than a traditional scraper pulling today’s price list, which is part of why the tooling looks so different once you dig in.
Why AI Crawling Volume Is Exploding Right Now
The traffic numbers back this up more than I expected when I went looking. As of June 2026, Cloudflare Radar reported that automated requests had crossed 57.5% of all HTML web traffic, ahead of human visitors for the first time on record. Of verified bot traffic, researches show AI crawler activity at around 20.3%, plus another 6.5% from AI-search bots, close to 27% of all verified bot activity tied to AI in some form.
Here’s the part that surprised me: most of that traffic isn’t answering anyone’s question in real time. Cloudflare’s May 2026 numbers attributed the majority of AI crawler requests to model training rather than to live search retrieval, and a separate read of Q1 2026 data put training-focused crawling at nearly half of all AI bot traffic. A traditional scraper exists to pull today’s prices. A huge chunk of AI web crawling exists to build a dataset nobody will look at for months.
On the tool’s side, the difference shows up in speed and accuracy too. AI-assisted extraction is reportedly running 30–40% faster than hand-built scrapers on comparable jobs, and dynamic pages that used to require constant selector rewrites are being handled with up to 99.5% accuracy. Maintenance, historically the real cost of running any scraper, is down roughly 40% for teams that moved extraction-heavy work to AI pipelines.
A Real Example of the Difference
Picture a product listing page. A traditional scraper built against article.product_pod with p.price_color for the price works great, right up until a redesign renames those classes. Then it returns nothing, silently, and someone downstream notices the price feed died a day later. Point an AI site crawler at the same page with “extract product name, price, and star rating,” and it doesn’t care what the class is called. It recognizes a repeated block with a name, a currency figure, and a rating, and keeps extracting straight through the redesign.
That resilience isn’t free, though. The AI system costs more per page, and you get less visibility into exactly how it decided a given field was “the price.” For financial data or anything compliance-sensitive, that opacity is a real problem, not a minor tradeoff.
When to Use Which
Stick with a traditional scraper when the target site is stable, you’re running huge page volumes where per-page AI cost adds up fast, or you need to be able to point to the exact rule that pulled a given field.
Reach for AI crawling, or more realistically, a hybrid, when the site’s layout changes often, the content is inconsistent, or you need something working in days without an engineer writing selectors.. Most production setups I’ve seen land on a hybrid: traditional scraping for the big structured pulls, AI extraction for the messy long tail.
If you’re evaluating vendors, just ask them directly whether their product supports AI web crawling natively or is a traditional scraper with an AI layer bolted on for edge cases. The answer tells you a lot about how much maintenance you’re actually signing up for.
What This Means If You Publish Content
This shift matters even if you never run an extraction pipeline yourself, because it changes how your own content gets found. Robots.txt was written for search indexers, not for AI crawling systems that distinguish between training and retrieval. Cloudflare now blocks unverified AI bots by default on new domains, and licensing standards like RSL (Really Simple Licensing) are showing up specifically so publishers can signal permission at the crawler level. If getting cited by AI answer engines matters to you, understanding how an AI web crawler actually reads and attributes your pages belongs in your technical SEO checklist now, not as an afterthought.
The Bottom Line
Traditional web scraping tools pull from where data sits. AI crawling systems pull from what the data means. The first is cheaper and easier to audit at scale. The second survives redesigns and needs far less monitoring. Which one you actually need depends on how stable your target site is and how much of your team’s time you’re willing to spend keeping selectors alive.
FAQ
Yes. Both terms describe the same thing: a system that pairs browser automation with a language model to interpret page content rather than relying on fixed HTML selectors.
No. Traditional tools are still cheaper at very high, stable-structure volume. Most teams run both and pick per job.
Because most of it feeds model training, not live answers. Cloudflare’s 2026 data put training-related crawling above half of AI web traffic.
Make sure robots.txt isn’t blocking the AI user agents you actually want indexed, check server logs for crawler activity, and look at RSL or similar licensing signals if you want to control how your content gets used for training.
