
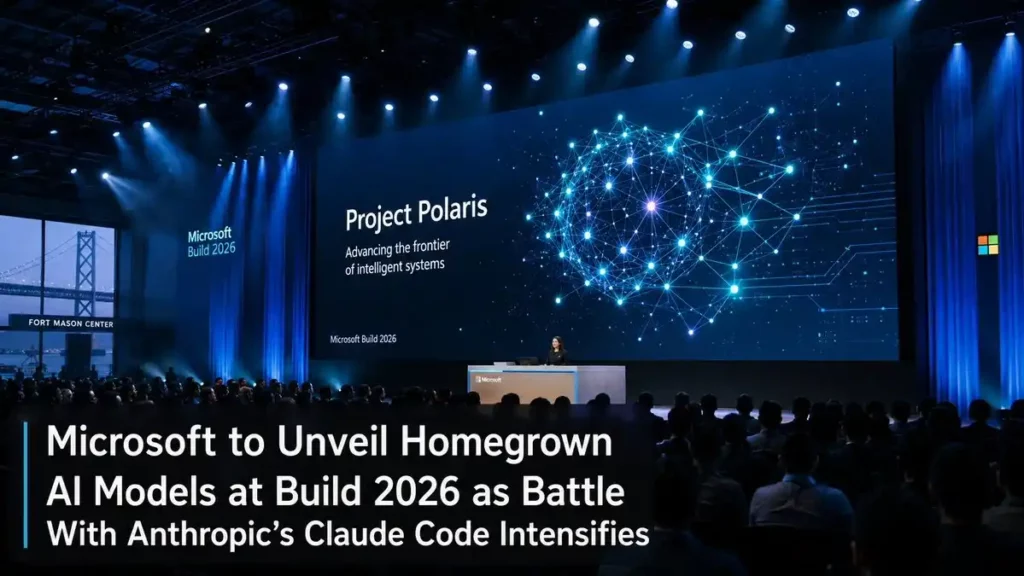
I want to tell you something that surprised me when I first read it: Microsoft publicly named Claude Code as the competitor and developed Project Polaris to displace it. Not as an aside. As the stated motivation. That kind of naming takes confidence or desperation, and I’m still not sure which one this is.
Project Polaris is Microsoft’s first in-house AI coding model. It’ll power GitHub Copilot starting August 2026, replacing GPT-4 Turbo as the default reasoning engine.
In this blog, we’ll dive into Project Polaris, why it was built, and learn about both the upsides and downsides of Microsoft’s first AI coding model.
Key Takeaways
- Project Polaris is Microsoft’s first homegrown AI coding model. It isn’t a general-purpose model with a coding plugin attached.
- It’ll replace GPT-4 Turbo inside GitHub Copilot in August 2026, with an optional three-month fallback to GPT-4 Turbo till November 2026.
- Architecture: mixture-of-experts (MoE) with language-specific submodules, chain-of-thought and tree-of-thought reasoning at inference, and Azure Maia accelerators.
- Microsoft hasn’t published SWE-Bench Verified, LiveCodeBench, or HumanEvalPlus scores yet; only the internal benchmarks are available.
- The Code Content Guarantee indemnifies enterprise AI customers against IP claims on Polaris output, which is a direct unlock for regulated industries that froze Copilot rollouts.
- Turing Forge, the companion fine-tuning service, lets organizations train Polaris on their own codebase inside a secure VPC.
- GitHub Copilot has 4.7 million paid subscribers and 90% Fortune 500 penetration. Polaris lands inside all of them automatically.
What Is Project Polaris?
Project Polaris is a domain-specialized AI coding model built by Microsoft from the ground up, and not as a general-purpose frontier model with a coding layer added on top. It uses a mixture-of-experts (MoE) architecture with language-specific submodules. This means that different parts of the model will handle different programming languages independently rather than routing everything through a single generalist system.
During inference, Polaris will apply chain-of-thought and tree-of-thought reasoning to work through multi-file refactoring tasks. And it’ll run on Microsoft’s custom Azure Maia accelerators to keep inference cost manageable at Copilot’s scale. It’s the AI coding assistant layer inside GitHub Copilot, and not a standalone agent like Claude Code or OpenAI Codex.
Why Microsoft Built Its Own AI Coding Model
Three things pushed Microsoft here, and none of them happened slowly.
First, Claude Code overtook GitHub Copilot in developer adoption for agentic coding tasks. This wasn’t some rumor. Microsoft named it explicitly as the competitor, and it was built to displace Claude Code. When a company at Microsoft’s scale publicly benchmarks against an 18-month-old product from a smaller competitor, that’s basically admitting to a setback from a smaller competitor.
Second, the Microsoft-OpenAI partnership changed in a way that made exclusive model access no longer a viable strategy.
And third, the per-token economics of routing millions of Copilot completions through OpenAI’s API have real costs, and owning the model eliminates that overhead permanently.
The Microsoft-OpenAI partnership shift
On April 27, 2026, Microsoft and OpenAI restructured their partnership. The most important change was that OpenAI can now distribute its models through AWS and Google Cloud. Exclusivity to Azure is now gone.
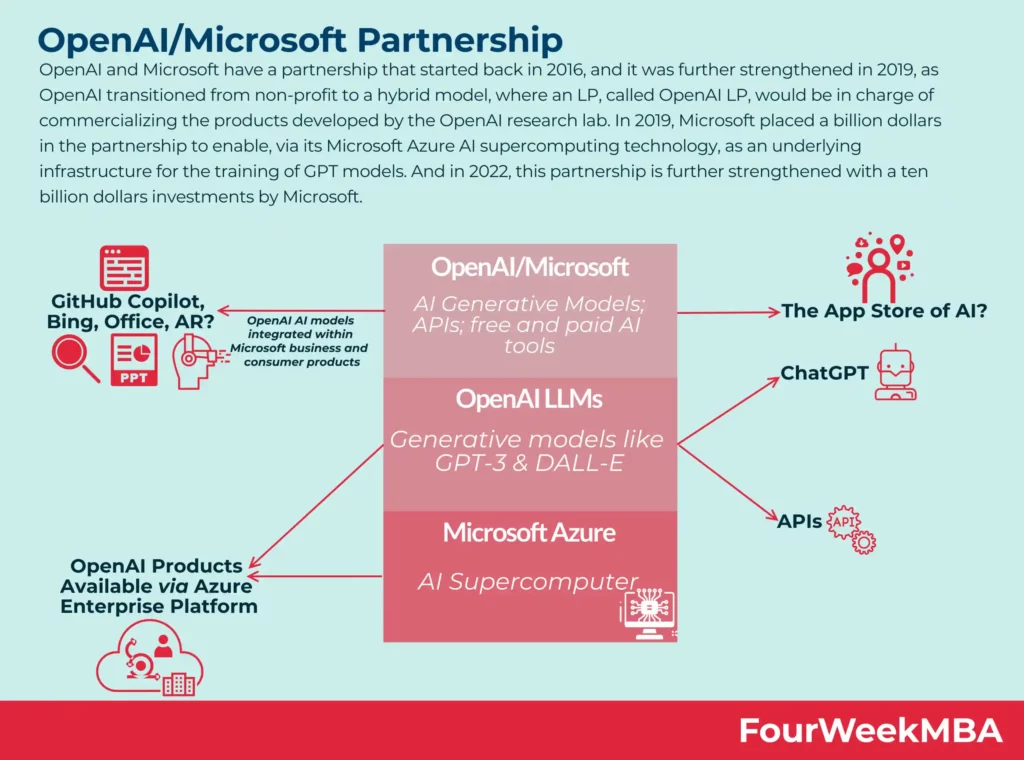
Microsoft could no longer differentiate GitHub Copilot through exclusive model access. If the same OpenAI models run on AWS, any AI developer tools startup can build on identical infrastructure. Building a proprietary model stops being a roadmap item and becomes a structural necessity. Project Polaris is the coding piece of that answer.
What Microsoft Announced at Build 2026 for Developers
Project Polaris was the headline, but it was one of five concrete developer launches at Microsoft Build 2026. It matters because several of these interact with how Polaris will be used:
- Project Polaris: Microsoft’s first in-house AI coding model. New default reasoning engine in GitHub Copilot from August 2026. Replaces GPT-4 Turbo.
- GitHub Copilot Workspace exits beta to GA: Two new run modes ship with it. Fleet handles autonomous CLI orchestration of multiple agents against a repo. Autopilot runs scheduled background jobs. Both are powered by Polaris once it lands.
- Windows Agent Framework v1.0 open-sourced under MIT: YAML-defined agents that move from a developer laptop to a Windows 365 Cloud PC to an Azure Arc edge device without rewriting. It also includes a cross-agent communication bus on gRPC and a declarative agent manifest.
- Windows Agent Runtime Insider preview: OS-level APIs that let agents see the taskbar, file system, and task scheduler. Only the text-based preview was shown in Microsoft Build 2026, with multi-modal screen interaction planned for later previews.
- Windows Agent Store: Launches with an 85/15 revenue split and a Microsoft security review for every listed agent. Adobe and Zoom named as launch partners.
How Project Polaris Works: Architecture Explained
Understanding the architecture is worth it here, because the design choices tell you specifically who Polaris is for and what problems it was actually built to solve.
Mixture-of-experts design and why it matters for AI code generation
In a standard language model, every token routes through the same set of parameters regardless of what language or framework you are working in. But in an MoE system, a router selects a specialized submodule based on the input context, and only that submodule activates.
For AI code generation, this pays off most on low-resource languages, like Rust, Haskell, and Go, languages where a single generalist model runs out of high-quality training signal and starts hallucinating APIs that don’t exist. The same MoE architecture powers both Kimi K2.6 and DeepSeek V4. So the design has proven results outside of Microsoft’s own claims.
Chain-of-thought and tree-of-thought reasoning at inference
Chain-of-thought gives the model internal step-by-step reasoning before it produces an output. Tree-of-thought goes a bit further. It branches into multiple candidate solution traces in parallel and selects the best one before returning a result.
In reality, this matters for multi-file refactoring. That’s the specific workflow where current GPT-4 Turbo-powered Copilot has lost ground to Claude Code. Refactoring across ten or twenty files requires maintaining consistent context about what changed where and why. CoT plus ToT is how you build a model that can hold that context, reason through the consequences step by step, and branch when there are multiple valid approaches.
Project Polaris vs. Claude Code vs. OpenAI Codex: Side-by-Side Comparison
Fyi, Polaris is a model, not an agent. Claude Code and OpenAI Codex are standalone agents with their own CLIs, and in Codex’s case, Computer Use surfaces. So, comparing Polaris to Claude Code directly is like comparing a car engine to a car. The right comparison is GitHub Copilot powered by Polaris vs. Claude Code vs. the Codex CLI.
| Dimension | GitHub Copilot + Polaris (Aug 2026) | Claude Code (Anthropic) | OpenAI Codex CLI |
| Layer | Model inside an IDE assistant | Standalone CLI agent + IDE plugin | Standalone CLI + hosted Codex agent |
| Default Surface | VS Code, Visual Studio, JetBrains, GitHub.com | Terminal, IDE plugins, claude.ai | Terminal, VS Code, ChatGPT Mac/Windows/iOS/Android |
| Default Model | Polaris (MoE, CoT + ToT) | Claude Opus 4.8 / Sonnet 4.6 | GPT-5.1 family + Codex-tuned variants |
| Multi-file Agent Loop | Copilot Workspace Fleet + Autopilot (GA June 2026) | Native (workspace + repo plans) | Native (codex CLI + hosted Codex) |
| Computer Use | Not announced | Limited via tool use | GA on Mac and Windows (May 2026) |
| Pricing | Bundled inside Copilot Business / Enterprise seat | Anthropic Pro, Max, or API per token | ChatGPT Plus / Pro / Business or API per token |
| IP Indemnification | Code Content Guarantee (new, Aug 2026) | Enterprise clauses available | Enterprise clauses available |
| Strongest Claim | Latency and cost at Copilot scale, low-resource languages | Multi-file agentic refactor, planning quality | Long-running autonomous runs, Computer Use |
The table tells you where each tool is strongest. It doesn’t tell you which to use, because that depends on your workflow, not the marketing claim. That decision is in a later section.
The Code Content Guarantee and What It Means for Enterprise Teams
The Code Content Guarantee is Microsoft’s commitment that Polaris was trained on permissibly licensed code only, and that enterprise customers using Copilot output are indemnified against intellectual-property claims on what the model produces.
A significant number of large organizations froze or capped GitHub Copilot rollouts in 2024 and 2025 over training data liability concerns. And they had a valid reason for that. If a model trained on code scraped from public repositories reproduces a substantial portion of that code in your product, you may be liable for an IP violation. So the legal teams started asking for guarantees, which wasn’t possible under the previous setup.
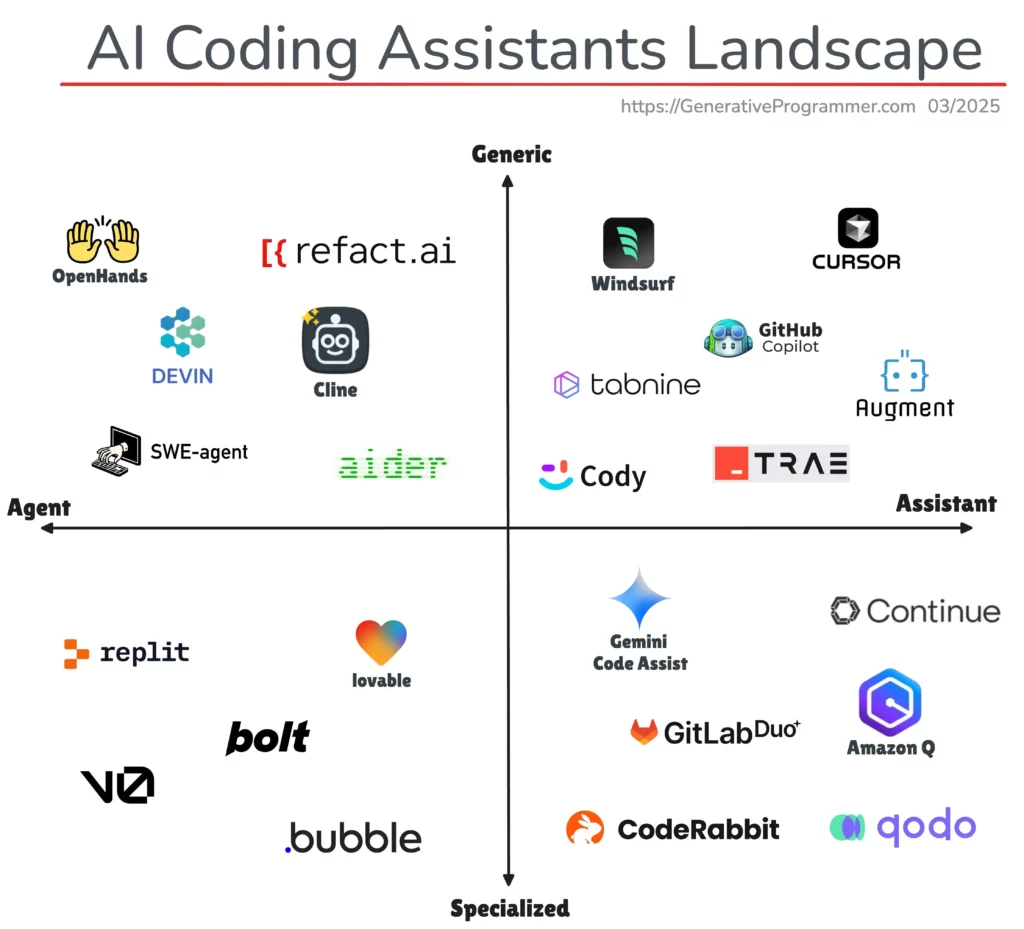
The Code Content Guarantee changes that calculus directly. It does not answer every question, and the details of what “permissibly-licensed” actually means in practice will require scrutiny. But it gives enterprise AI procurement teams a contractual signal they can use to unfreeze stalled rollouts. For any organization that has been blocked on enterprise AI coding tools for legal reasons, this is the most practically significant thing in the Polaris announcement.
What Polaris Does Not Tell You Yet: The Benchmark Gap
As of Build 2026, the only published performance claims are:
- Internal Microsoft benchmarks showing Polaris outperforming GPT-4 Turbo on HumanEval and MBPP, specifically in Rust, Haskell, and Go.
- No numbers for SWE-Bench Verified, LiveCodeBench, RepoQA, or HumanEvalPlus.
HumanEval and MBPP test isolated Python function completion on clean, constrained problems. They don’t test navigating a 50-file TypeScript monorepo or catching subtle logic errors across files you have not directly touched. That is SWE-Bench territory, and SWE-Bench is where real AI programming comparisons happen.
For context: Claude Opus 4.8 scores 69.2% on SWE-Bench Pro. That is the public benchmark Polaris needs to release for a credible head-to-head claim on agentic coding quality. Until Microsoft publishes that number, or a third party produces it independently, the performance story is one-sided.
Turing Forge: Microsoft’s Enterprise Fine-Tuning Layer for Polaris
The most strategically interesting part of the Microsoft Build 2026 announcement isn’t the Polaris model itself. It’s Turing Forge, the companion fine-tuning service.
Here is what it offers:
- Organizations fine-tune Polaris on their own codebase inside a secure VPC.
- Microsoft claims a minimum of 50 training examples for meaningful customization.
- Full IP indemnification applies to Turing Forge output.
The 50 training examples figure deserves skepticism. That number almost certainly comes from clean, well-structured repositories. Real enterprise codebases with legacy debt, inconsistent naming, and undocumented tribal knowledge will need significantly more.
The direction is right. Early pilot data from healthcare and finance organizations reported 40% reductions in code review turnaround time. For enterprise teams evaluating AI developer tools, that’s a concrete ROI signal neither Cursor nor Claude Code can match yet.
Project Polaris Rollout Timeline
The rollout timeline:
- August 2026: General availability for all paid Copilot subscribers. Default migration, no opt-in required.
- August to November 2026: An optional three-month fallback to GPT-4 Turbo for teams that need it.
- November 2026: Fallback window closes. Polaris becomes the only option.
For most individual Copilot users, this transition will be invisible. But for Copilot Business and Enterprise teams with CI pipeline integrations or prompt workflows, this is a real model swap. GPT-4 Turbo and Polaris will not behave identically on the same prompt. The window between now and August is the right time to build an evaluation baseline you can run against both models before the switch is forced.
Should You Switch From Claude Code or Codex to Polaris Now?
No, and here’s the specific reason. No independent benchmarks exist before the August GA. Any switch decision made today is based entirely on internal Microsoft claims.
The right call depends on where you are:
If you’re a GitHub Copilot user, you’re getting Polaris automatically. The action item is to set up an internal evaluation baseline now, using golden tests and code review benchmarks that reflect your actual codebase. That way you will know within the first two weeks of GA whether Polaris is better, worse, or the same for your specific use case.
If you’re using Claude Code or OpenAI Codex, nothing changes before August. Claude Code still has the strongest published numbers on agentic benchmarks, and the Codex Windows GA shipped in May 2026. So there’s no reason to move before you can compare Polaris on actual tasks.
For the next 90 days, track three things:
- Independent SWE-Bench Verified numbers for Polaris post-August GA.
- Turing Forge pricing when it enters enterprise AI preview.
- Windows Agent Runtime trajectory as an indicator of how deep the agentic layer goes in the broader AI developer tools ecosystem.
Final Thoughts
Project Polaris is Microsoft’s first real bet that it can compete on model quality inside GitHub Copilot rather than relying on third-party models. Whether it pays off comes down to one number: an independent SWE-Bench Verified score after the August 2026 GA.
If that number is competitive with Claude Opus 4.8’s 69.2% SWE-Bench Pro score, this is a real shift in the AI coding assistant landscape. But if it falls short, 4.7 million existing Copilot subscribers only buys so much time before developers move toward whichever tool does the work better.
FAQs
Project Polaris is Microsoft’s first homegrown AI coding model, announced at Microsoft Build 2026. It is a mixture-of-experts model that replaces GPT-4 Turbo inside GitHub Copilot starting August 2026.
August 2026 for all paid subscribers via automatic migration. Polaris becomes the sole default after November 2026, with an optional fallback to GPT-4 Turbo available until that time.
Direct independent tests are not yet available. Polaris is an underlying model layer powering GitHub Copilot, whereas Claude Code is a standalone AI agent. Independent SWE-Bench Verified scores post-August 2026 GA will be required for a true head-to-head comparison.
Microsoft’s IP indemnification for Polaris output. Polaris was trained on permissibly licensed code, and enterprise AI customers are covered against copyright claims on model-generated output.
Turing Forge is a VPC-based fine-tuning service for Polaris. Organizations train the model on their own codebase with a claimed 50-example minimum. Primarily targeted at regulated industries.
Not confirmed. No standalone availability in Azure AI Foundry has been announced. No agent SDK for Polaris was disclosed at Build 2026.
